Instagram Scraping: Pull Public Data Without Instant Blocks
Instagram scraping is collecting public profile fields, posts, captions, and hashtags with a script. Blocks usually come from a datacenter exit, a new IP on every profile, or a burst of GraphQL hits. Log status and body first. Keep one residential session for one profile job, then rotate between jobs.
Key Takeaways
- Instagram scraping pulls public pages. The Graph API is for accounts you manage.
- Empty JSON with HTTP 200 is a parse miss. A login wall is a block.
- One profile job keeps one IP. Rotate after the user is done.
- An Instagram scraper still fails if the exit is a datacenter ASN.
What Instagram scraping is
Instagram scraping is automated collection of public Instagram pages. The job returns a username, biography, follower count, post captions, media URLs, timestamps, and hashtags that load in a logged-out browser. If the profile is public and the HTML or embedded JSON shows those fields without a password, treat it as in scope. A script issues HTTP or a maintained library.
An Instagram profile scraper is the client that reads those public homepage fields. Auto likes, follows, and posting hit action limits on a logged-in account. Meta terms restrict automated collection without permission. Do not steal another user’s session cookie. Do not drive a login wall that is not yours. Do not pull private profiles, DMs, or a full follower graph.
When do you use the Graph API instead of Instagram scraping?
The Instagram Graph API is Meta’s supported interface for Professional accounts you manage. It returns media, comments, mentions, and insights for Business and Creator profiles tied to your app. It cannot read consumer personal accounts. Instagram scraping here is the unofficial path for public pages the API does not list. Pick the API first when you own the account.
Public third-party profiles and hashtag pages are outside that app. The Graph API does not return those logged-out fields. Mixing login, posting, or following into a scrape job can checkpoint the session you still need for reads.
Read Meta’s Instagram Graph API for accounts you manage. Meta’s terms restrict automated collection without prior permission. This is not legal advice. Stay on public pages you can open logged-out.
Why do Instagram scraping jobs get blocked?
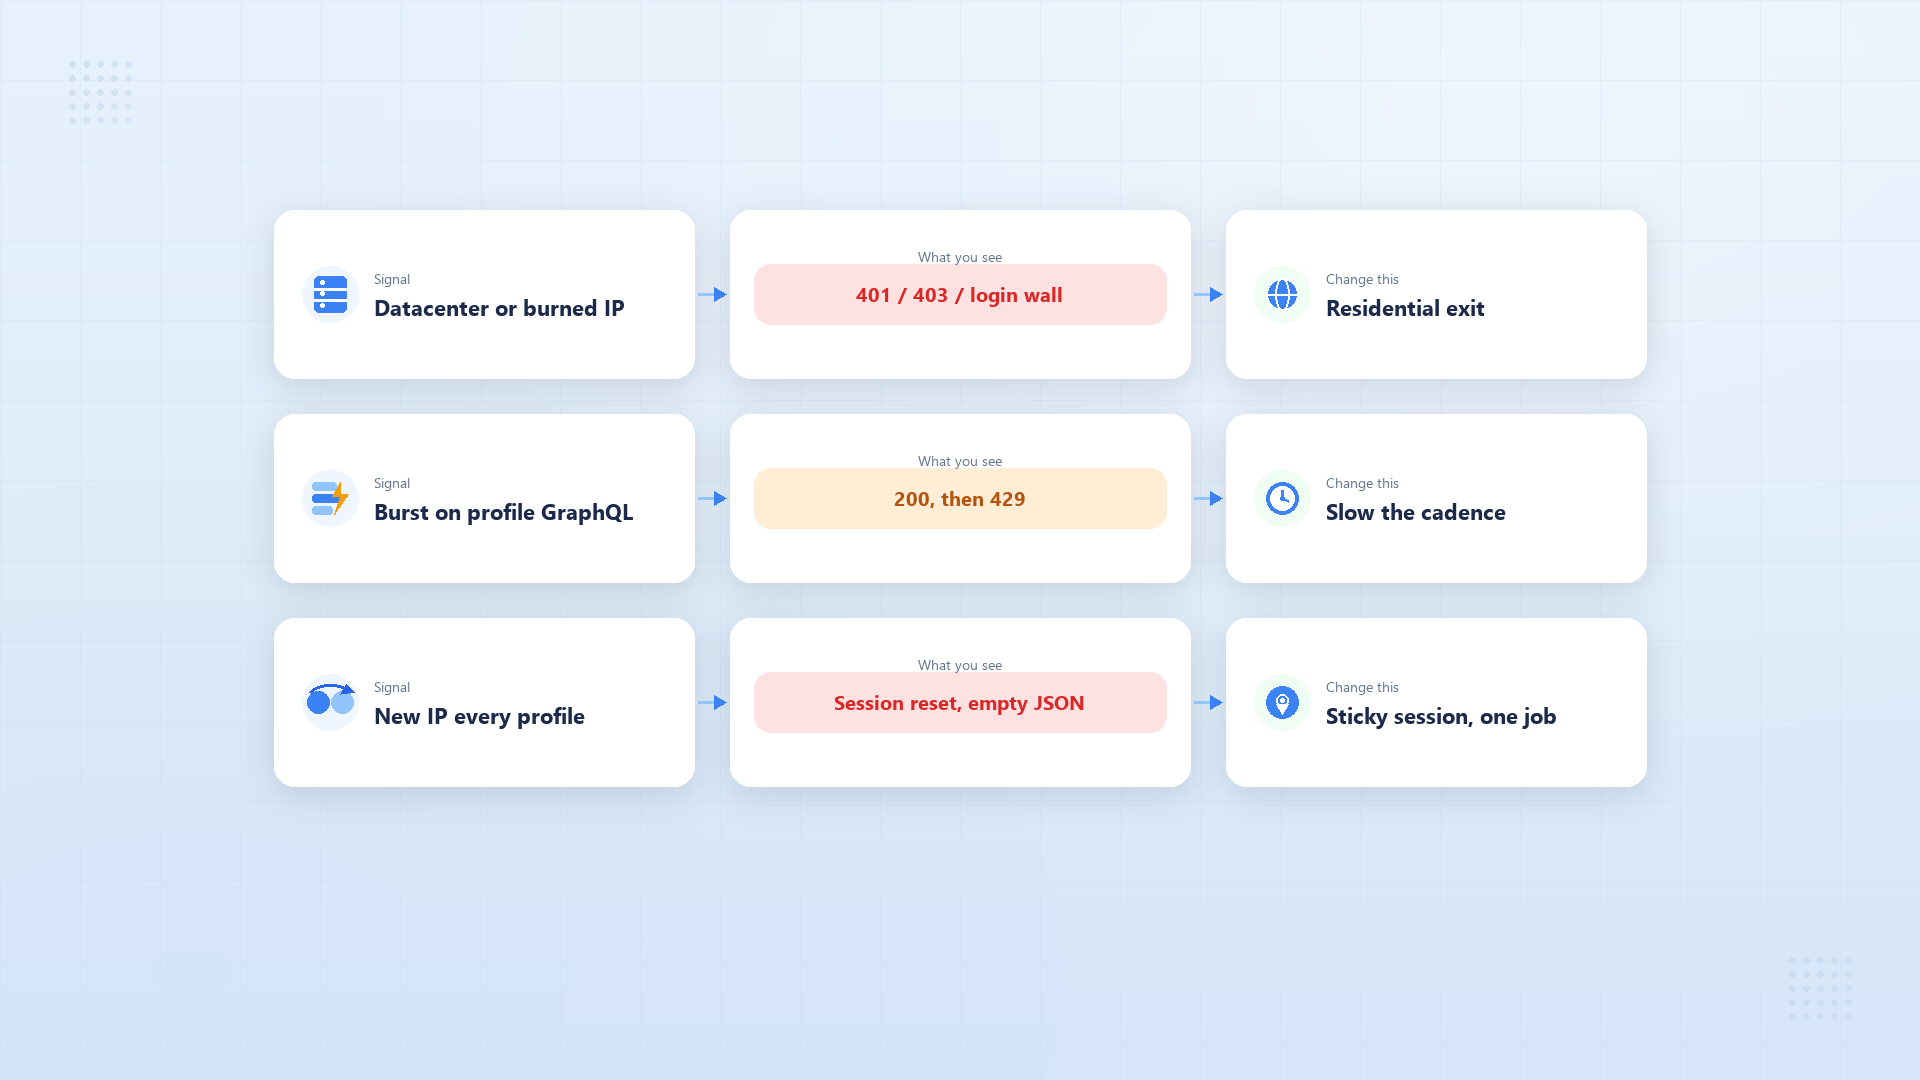
A block here means Instagram answered, but not with the public fields you asked for. You may get HTTP 401 or 403, 429, a login wall, a checkpoint, or a 200 with an empty payload. The edge is scoring the exit IP, how fast you repeat GraphQL or profile paths, and whether the client looks like a browser. A datacenter ASN on instagram.com is the usual first fail.
Three layers show up on public URLs. Hosting ranges and already blocked exits often fail on the first request. A burst on a profile or hashtag path can return 200 a few times, then 429. A new IP on every media id drops cookies and CSRF.
A login wall means the body is a sign-in shell. You do not have a browser session yet. Read a Cloudflare 403 as a refusal before you change selectors. Do not send the page to a captcha solver.
How do you tell a parse miss from a login wall?
A parse miss means the HTTP layer succeeded and your selector or JSON key missed the caption node. A login wall means Instagram swapped in a challenge or sign-in shell. Status code alone is too coarse. A 200 with a login form is still a block. Saving status, content-type, and a short body slice stops you from rotating IPs on a key rename.
- Hit one public profile URL once. Do not loop retries.
- Print status, content-type, and the first 200 characters of the body.
- Match that output to the table. Parse miss, login wall, or rate.
- Change the exit only on a block. Leave a parse miss on the client.
HTTP 407, or a tunnel that never opens, is a proxy user, password, or port problem. You have not reached Instagram yet. Check the exit IP if the tunnel itself is clean.
What should one Instagram scraping request look like?
An Instagram scraper is the client that fetches one public profile and reads fields from HTML, embedded JSON, or a maintained library. It can be Python requests, Instaloader, or a hosted tool. Instagram still sees one IP, one TLS handshake, and one cadence. Put the proxy on that client. If the biography is already in the body, fix the parser first.
Use one public username. Do not call login(). Do not dump a follower list.
- Attach an HTTP or HTTPS proxy on the client. Use host:port:user:pass. Do not paste a live gateway.
- Fetch one public profile. Set download_pictures=False and cap the post count.
- Print username, follower count, and a truncated caption.
- Sleep between posts. Stop after a handful of rows.
Expected output is one username, a follower count, and a few caption lines. HTTP 200 plus those strings is a fetch. 407 is proxy user, pass, or port. 401, 403, or 429 go back to the signal table. A login form in the body means fix the session before you chase JSON keys.
If every new IP still returns a login wall, run the job in a real browser stack. Do not raise concurrency on a 401.
How do you keep one session for a profile job?
A session here means Instagram treats a run of public URLs as one viewer: same exit IP, same cookies, same locale. Instagram scraping across several posts on one profile needs that continuity. A new IP on every media id looks like a new device on every request. Sticky means same IP for one job. After the job, you open a new session.Start from the status and body you already logged.
- Parse miss: stop. Fix the key or selector.
- Datacenter hard 401 or 403: move to a residential exit.
- Every new IP is a login wall: change the browser stack. Do not add workers.
- A few 200s, then 429: keep one session and slow the queue.
- Profile job finished: open a new session for the next user.
Run the profile job on a sticky residential session so one user keeps one exit until you store the fields. IPOasis sticky, up to 120 minutes. It starts at $0.78/GB. Unused traffic does not expire. When the window ends, the IP can change. Open a new sticky session for the next job.
Teams that collect public Instagram data from more than one region still pin one session per profile. Match locale to the exit country. Do not point a US client at a JP IP and expect the wall to clear.
If a residential ASN still hits a checkpoint on a public job, switch to a mobile exit. Mobile starts at $0.88/GB. Use it after the residential session fails.
FAQ
What is Instagram scraping?
Instagram scraping is automated collection of public profile fields, posts, captions, and hashtags. The client stores strings that already load in a logged-out browser. The Graph API covers accounts you manage. If the page needs a password, it is out of scope. Log HTTP status before you treat an empty caption as a block.
Is Instagram scraping legal?
This is not legal advice. Public pages you can open without logging in are the usual monitoring case. Meta’s terms still restrict automated collection without permission. Do not steal session cookies. Do not drive a login wall that is not yours. Read the current terms before you schedule a job.
Can you scrape Instagram without the Graph API?
Yes for public pages the Graph API does not list. The API covers Professional accounts you manage. It cannot read consumer profiles. A logged-out fetch is a different path, with blocks and parser drift. Prefer the API when you own the Business or Creator account.
How long should one profile job keep the same IP?
Keep the same IP for one profile job, meaning one user or one hashtag run. Sticky means same IP for one job. When the job ends, open a new session. Do not rotate inside a post list. Do not pin one IP across unrelated users unless you need that.
Why are captions missing when the status is 200?
HTTP 200 means the server returned a body. The caption can still be missing if your key missed the node, or if the body is a login wall. Save content-type and the first 200 characters. If the caption string is in the HTML or JSON, fix the parser. If the body is a sign-in shell, treat it as a block.
Do I need an Instagram scraper or a browser job?
An Instagram scraper here is any client that fetches a public profile and reads the fields. Instaloader or requests is enough when the biography is in the first body. If every new IP still returns a login wall, a plain HTTP client is not enough. Switch to a real browser stack for that job.
Do I need a mobile proxy for Instagram scraping?
A mobile proxy is a carrier exit. For public metadata, start with a sticky residential session for one profile job. Switch to mobile when that residential ASN still hits a checkpoint. A biography fetch does not need a carrier IP on the first request.
Conclusion
Split a parse miss from a login wall before you change the exit. Keep one residential session for one profile job, then open a new session for the next user. When you need that exit, run the profile job on a sticky residential session.